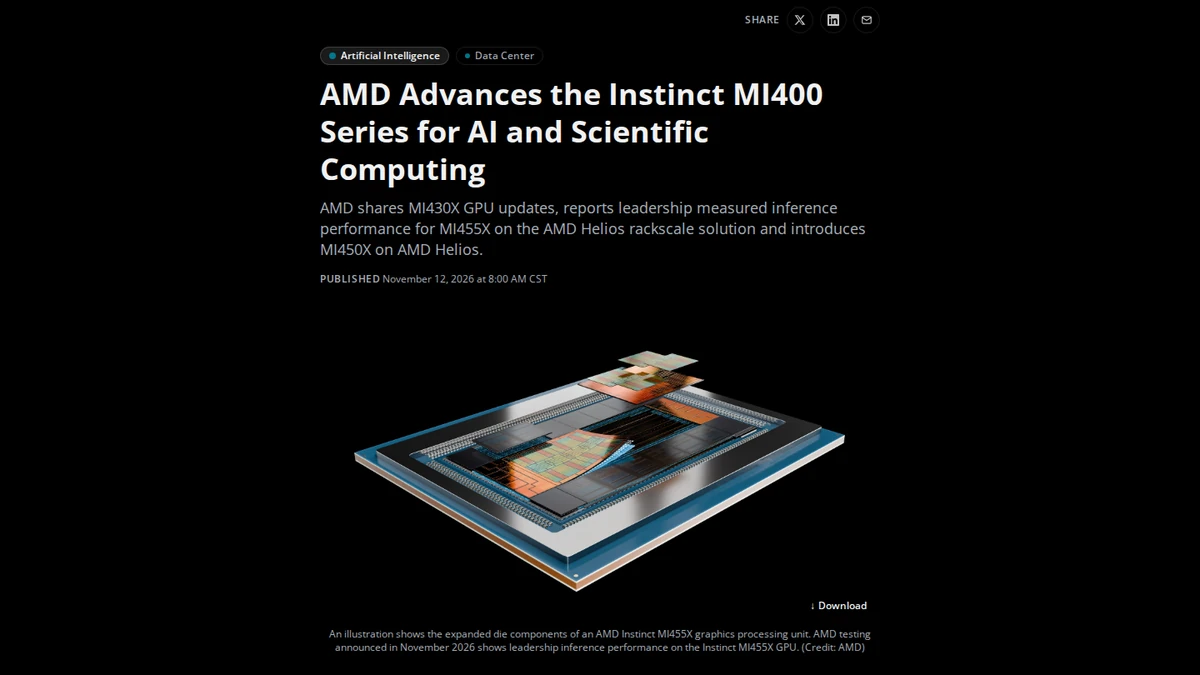
AMD expanded its Instinct MI400 GPU portfolio on November 12, introducing the MI450X as an additional option for Helios rack-scale AI systems. The company said MI450X has 288 GB of HBM4 memory and shares core compute and connectivity capabilities with the larger-memory MI455X.
The announcement also presented fresh MI455X inference figures. AMD reported 21,333 tokens per second per GPU on a DeepSeek-R1 workload using an AMD-tested MLPerf Inference Offline configuration, and claimed throughput up to 30% higher than a published NVIDIA Vera Rubin result.
Those comparisons require careful qualification: AMD ran its own benchmark and compared it with NVIDIA's published submission, rather than a single independent test with all conditions controlled. Offline throughput is not necessarily representative of interactive latency, power consumption or end-to-end deployment cost.
For scientific computing, AMD provided more detail on MI430X, including native double-precision compute, 432 GB of HBM4 and up to 23.3 TB/s of memory bandwidth. These characteristics target workloads where numerical precision and large scientific datasets matter alongside AI acceleration.
The broader strategic change is portfolio segmentation. AMD is offering different memory and precision profiles for AI inference and scientific workloads, seeking to compete for accelerator deployments where hardware configuration, software maturity and total cost of ownership all influence buying decisions.