AI Singapore and NVIDIA have released Nemotron-SEA-LION-v4.8, a pair of open-weight mixture-of-experts models intended to improve language coverage and reasoning for Southeast Asia. The release includes 30B-A3B and 120B-A12B variants, indicating total and active parameter counts.
Regional post-training is the core change
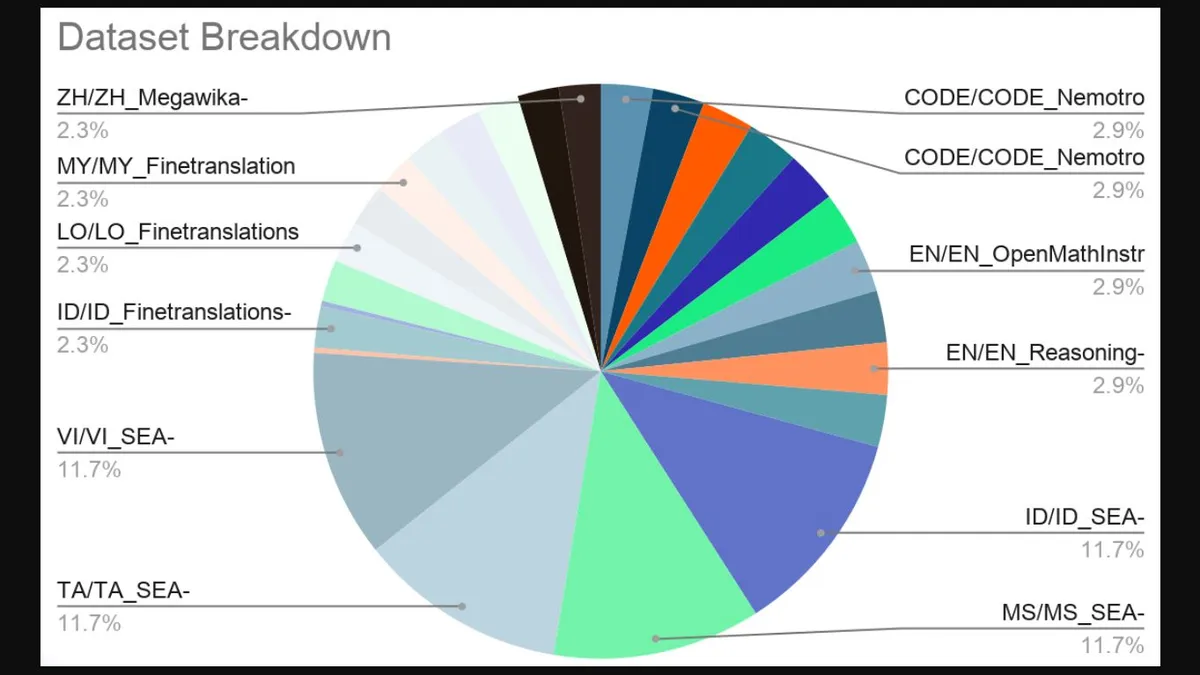
AI Singapore says the models build on NVIDIA Nemotron bases and add continued pre-training and post-training data for Southeast Asian languages and cultural contexts. The 120B model card lists a 262,144-token context window and an MIT license.
Artifacts are public and traceable
Model weights and documentation are available on Hugging Face, while an accompanying technical report documents the training approach and evaluations. That makes the release inspectable, but it does not by itself validate every quality or safety claim.
Benchmark gains remain first-party results
The paper reports higher SEA-HELM aggregate scores after regional adaptation, including 46.06 to 51.57 for the 30B model and 49.30 to 63.44 for the 120B model. These are author-reported evaluations; no independent reproduction was located for this edition.